Dear friends,
Moving forward on early stage, 0-to-1 projects and mature projects requires very different tactics. For those who aspire to be skilled at AI Engineering, I've found that selecting the right tactic based on stage of project is one of the hardest but most important things to learn.
In the 5 letters on the AI Engineering Skills Map, you may have noticed calibration to the project stage was a recurring theme. This letter explains why. For many AI engineering tasks, like building evals, choosing software architecture, or getting product feedback, the right option usually depends on the project stage.
Take the task of evaluating an AI system — say, an automated customer-service email system. In an early-stage project, you might manually examine a dozen examples and check how sensible they are. A later-stage project might have hundreds of test examples and a written rubric for judging the quality of AI-written emails. A mature product might have tens of thousands or more test examples, a more detailed rubric, and rigorous processes for evaluating not just the quality of an email but its downstream effects (such as whether it causes a customer to be more likely to return).
Calibrating to the right stage of a project is important for many other AI Engineering skills. It is not helpful to over-design at the early stages, or under-design a mature product. For an early stage project, if your primary goal is to quickly test a product idea, a casual software architecture design might be okay, with minimal thought given to efficiency, data schemas, cost of third party services, and so on. But as a project matures, giving careful thought to tradeoffs like latency, availability, consistency, reliability, maintainability, simplicity, and cost will give you a better outcome.
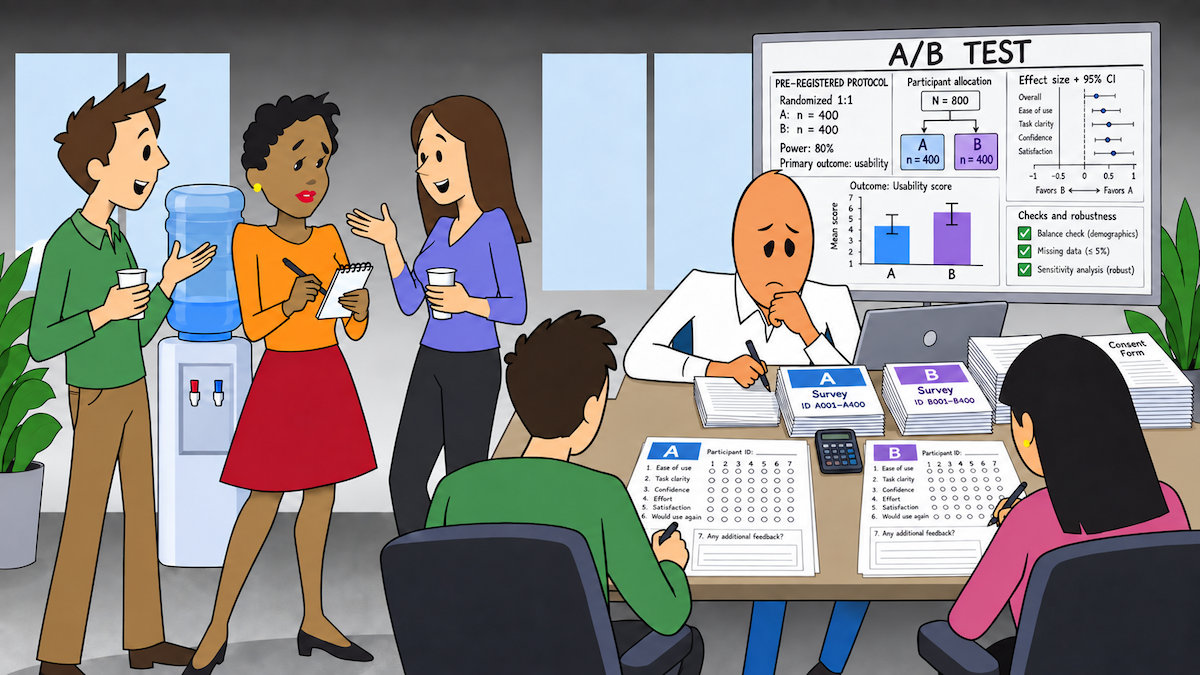
Similarly, getting product feedback can range from pulling aside 2-3 people and asking what they think, to running large-scale user studies, A/B tests, and analyzing product usage data.
One way to gain experience with different approaches is to work on different projects spanning early stage and mature ones. Someone working in a startup might learn the quick ways to do evals, and someone in a large company the best practices for slower, more rigorous approaches. I have seen engineers from large companies jump into startups and ask for overly slow/rigorous approaches. Similarly, engineers from startups may move to large companies but see their applications hit a performance ceiling until they learn to go past quick, but less accurate, ways of doing evals. Project experience is valuable, but if you don't want to have to take years to gain experience in both small and large companies to master this breadth of skills, DeepLearning.AI is here to help!
Every week, I am in discussions about products that serve 100M+ users as well as products that do not yet have any users. The operating cadence is very different for these types of projects! This is why corporate policies that mandate a one-size-fits-all approach, like requiring certain types of testing before anything can be shipped, can be counterproductive.
Given that even large companies should have small, innovative projects, it's worthwhile for everyone to learn the fast, efficient tactics that let small teams move quickly. At the same time, to avoid hitting a ceiling and being unable to develop your projects beyond a certain point, it is also worth knowing how to do things in a slower, more rigorous way.
Keep building, and I hope some of your early stage projects turn into large, successful mature ones!
Andrew
A MESSAGE FROM DEEPLEARNING.AI
Give your AI application a memory of its experiences, stored entirely on the device. In “Building AI Assistants with On-Device Memory,” turn text and images into vectors, search them by meaning, and teach it to recognize new objects from a few photos. Enroll for free
News
Claude Opus 5.5 Leaps Forward
A week and a half after CEO Dario Amodei proposed slowing down AI development, Anthropic released an AI model that promises to be first in a larger family.
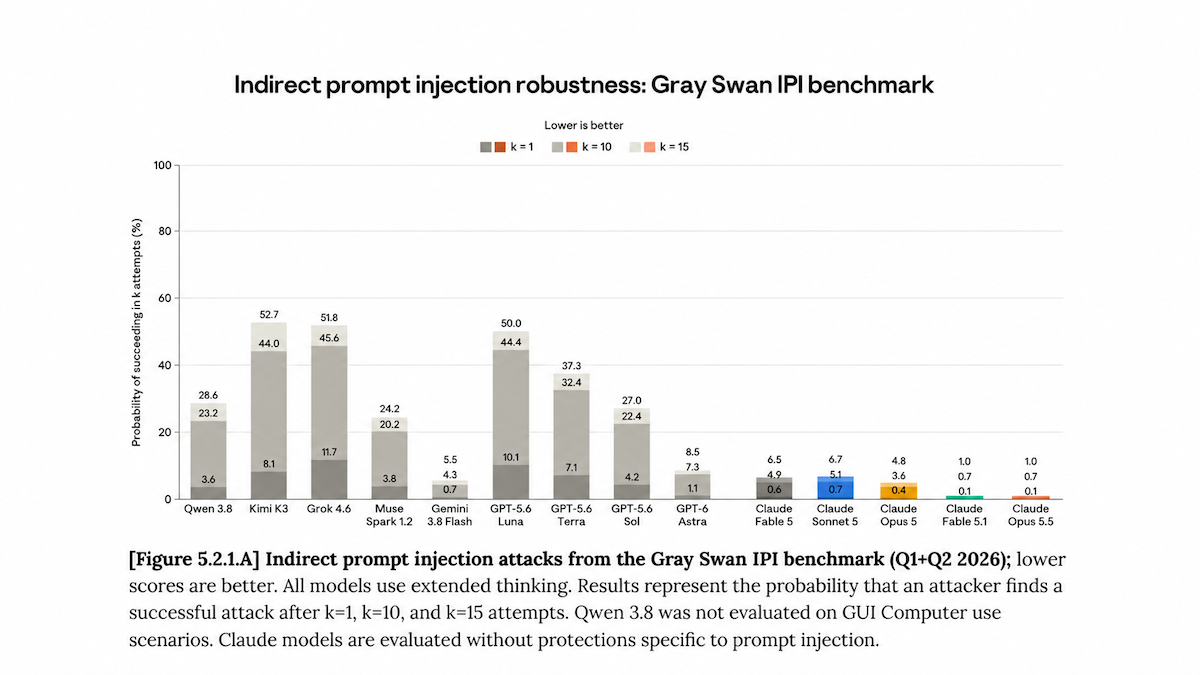
What’s new: Anthropic introduced Claude Opus 5.5, a lower-cost successor to Claude Opus 5 that outshines Claude Fable 5.1 and all other current models in overall intelligence. Unlike Fable, it doesn’t retain users' data for 30 days, but similar to Fable, it falls back to Claude Opus 4.8 for what Anthropic deems sensitive cybersecurity and biology queries.
How it works: Anthropic trained the model on private and public datasets, including data from public websites gathered with their ClaudeBot web crawler, synthetic data generated by other models, and data gathered from Claude users who haven’t opted out from allowing training on their inputs and outputs. The knowledge cutoff date is identical to Claude Fable/Mythos 5.1’s, suggesting the models were trained on similar datasets. After training, the company fine-tuned the model to align with values it defined using a constitution. It was also safety-tested by evaluators selected by Anthropic, including METR and Frontier Design.
Performance: Both Artificial Analysis and Vals AI rank Claude Opus 5.5 first among all models in their weighted evaluations of overall intelligence.
Behind the news: Claude Opus 5.5 arrived on the same day as OpenAI’s GPT-6 Sol and GPT-6 Luna, both less expensive models whose predecessors were rivals to Claude Opus 5, but both of which Claude Opus 5.5 now easily outperforms. These models were announced despite recent public calls from both Anthropic CEO Dario Amodei and OpenAI CEO Sam Altman, among other leading AI figures, to slow AI development to allow for further safety and security testing. If these releases are any indication, we won’t be lacking for new, highly capable models anytime soon, even if they may come with restrictions.
Why it matters: It’s a big deal any time we have a new best model on the market, and Claude Opus 5.5 appears to be significantly better than the rest. Business customers working with sensitive data, or anyone that doesn’t want to share inputs and outputs with Anthropic, will be pleased that Fable’s data retention policies don’t extend to Opus. Claude models have long been great coders, but this model seems to be particularly good at knowledge work — creating documents and presentations, crunching data, and doing research, all areas where Anthropic had recently ceded ground to OpenAI.
We’re thinking: From a benchmarking standpoint, it’s impossible to know just how capable Claude Opus 5.5 would be, particularly at cybersecurity and biological tasks, if it didn’t fall back to Claude Opus 4.8. It’s also important that legitimate safety, biomedical, and AI engineering work may be refused out of fears that users will use the models in ways Anthropic doesn’t want them to.
Models Built to Do One Thing Well
While most companies focus on generative and reasoning models, one company is betting on a class of models that isn’t either. All this new model does is analyze text and return answers to questions about it, but at higher speed and lower cost than a large language model.
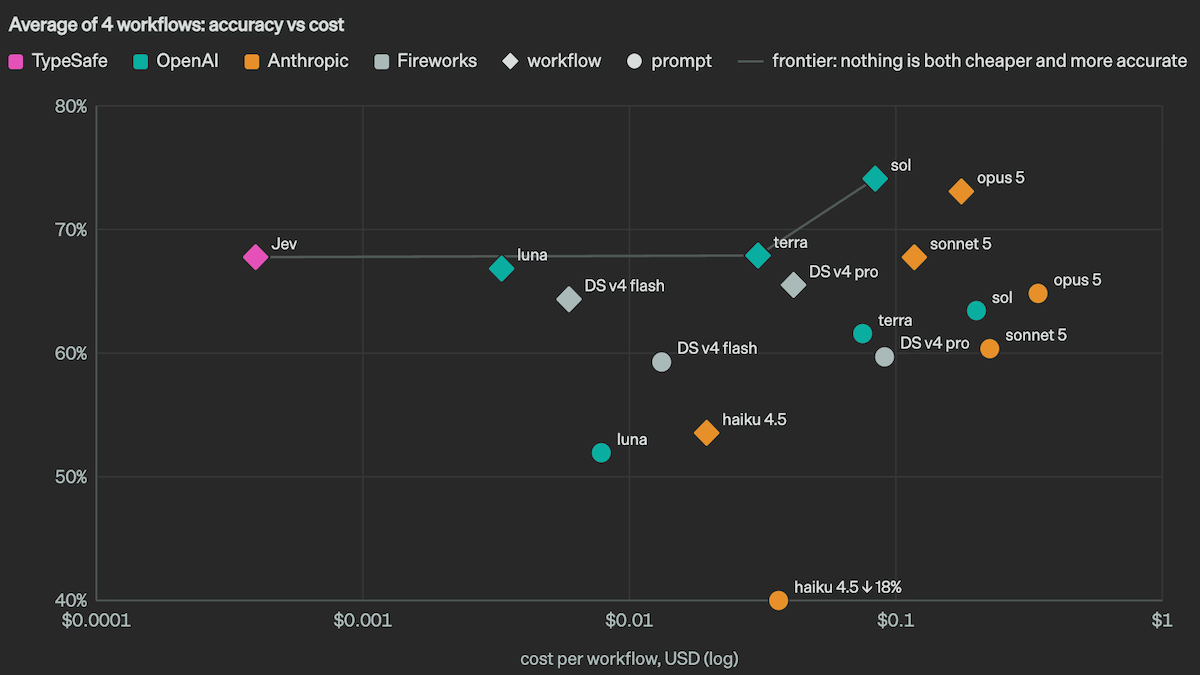
What’s new: TypeSafe, founded by OpenAI alumnus Diogo Almeida, released Jev, a general classification model that can answer any question with predefined outputs. It’s designed to be used to give other software tools enough data to make decisions, rather than as a general-purpose language model.
How it works: TypeSafe does not describe the architecture of Jev beyond saying it is not an LLM and not autoregressive, but it is transformer-based. The authors don’t describe their training data beyond saying they make it all themselves. They describe just one of their training methods, which they call “reinforcement learning for calibrated decisions” (RLCD).
Results: The authors only computed results for their models on their internal datasets, citing a number of reasons, including benchmark saturation and companies overly focusing on improving benchmark performance rather than general intelligence.
Behind the news: Shortly after Jev's release, a host of similar classification models hit the market, some of them open and local rather than proprietary. Laya focuses on multilingual support, but also claims higher accuracy and faster speed than Jev. Bespoke Nimble fine-tunes Qwen-3.5-9B to act as a classification model. Kev likewise uses Qwen 3.5 as a base, but in three different sizes, and attempts to reconstruct Jev's architecture. None of the models claim to have distilled Jev. Without a public benchmark, it's difficult to assess their performance. Meanwhile, platforms like Vercel and Cloudflare quickly added Jev support, replacing costlier LLMs for use cases like tool selection.
Why it matters: Before LLMs became hugely popular, most researchers focused on training one model that can do one or a small set of tasks well. When LLMs became popular, people’s opinions flipped, and the AI community started focusing on building one model that can perform any task well. TypeSafe takes a middle road: let’s build one model that can perform any classification task well. The company wrote a catchphrase to describe its approach to development: “Build prod, not god.”
We're thinking: Jev won’t replace modern LLMs. It can’t generate code, it can’t talk to people, it can’t act as an agent. Instead, it can detect jailbreaks, flag missing details, judge user satisfaction, and more — all situations where turning unstructured input into structured responses can be tremendously valuable for software engineers.
Learn More About AI With Data Points!
AI is moving faster than ever. Data Points helps you make sense of it just as fast. Data Points arrives in your inbox twice a week with six brief news stories. This week, we covered Alibaba’s open weights release of Qwen-Image 2.1 and the arrival of Xiaomi's MiMo-V2.6-Pro, the highest scoring open weights large language model. Subscribe today!
One Agent Works, Another Directs
Benchmarking a coding agent typically means scoring one model within one harness. Now a major independent evaluator has scored a harness that uses two models and found it matches top models’ performance at lower cost.
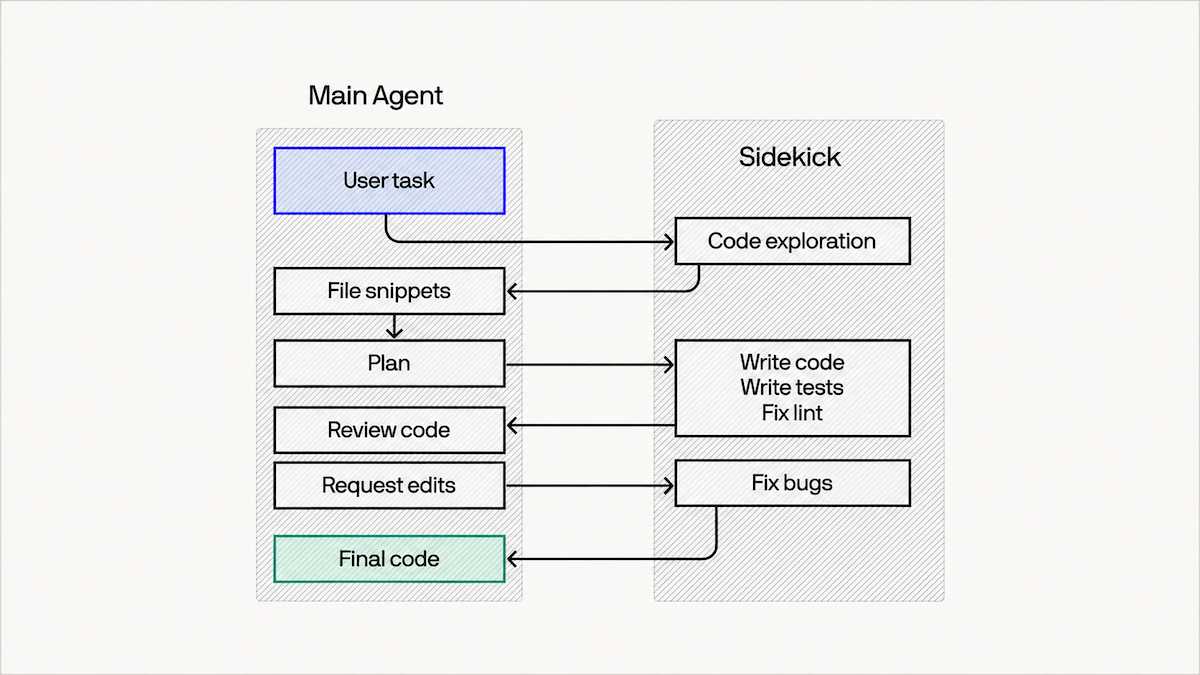
What’s new: Cognition introduced SWE-2, a model built for software engineering work, and made Devin Fusion, a harness that runs two models in one session, available beyond its cloud service. When using Devin Fusion, a more powerful model like Claude Fable 5.1 plans and reviews tasks, and a less costly one like SWE-2 carries out most of the work. All features below are for SWE-2, except where noted.
How it works: Instead of handing a task from one model to another in sequence, Devin Fusion runs two agents at once. A lead agent runs a planner model that oversees the session. A sidekick agent runs a cheaper model that completes lower-priority work. Each agent maintains its own tools and context.
Performance: Artificial Analysis independently ran two Devin Fusion pairings through its Coding Agent Index v1.5. Configured with Claude Fable 5.1 as the lead model, Devin Fusion matched Claude Code running the same model alone at a higher reasoning level and cost 36 percent less per task. Configured with GPT-6 Astra, Devin Fusion scored three points lower than Codex running Astra alone, again at a higher reasoning level, but cost 39 percent less.
Behind the news: Devin Fusion is not new, and Cognition is not the only company attempting to match frontier model performance at lower costs by blending multiple models.
Why it matters: With one model in a harness, token and dollar consumption grow together, so developers can monitor token use as a rough proxy for their bill. Fusion muddies these estimates because it burns lower-cost tokens at a higher rate. Artificial Analysis measured Devin Fusion with Claude Fable 5.1 as the lead, finding it consumed 70 percent more tokens and took nearly three times as many turns than Claude Code using Claude Fable 5.1 alone — but still cost less per task. You might think you could save money by using a sidekick model with a lower per-token cost, but that’s not necessarily true. SWE-2 appears to be the most efficient option for a sidekick model, both outperforming and costing less than models (for example, GPT-5.6 Luna) that are head-to-head more intelligent and cost less per token. In this case, developers really have to pick the right tool for the right job.
We’re thinking: Between Cognition and Sakana, we’ve seen two very different versions of an architect/worker model architecture, but both have succeeded by training companion models that do a specific job well, whether that job is giving instructions or following orders. Model specialization remains a powerful way forward and (as the multi-model Fugu already shows) could be further decomposed to move beyond a simple two-model worker-planner structure.
Agents Work Better When They Can Pass Each Other Notes
Large language models can work faster by dividing problems into sub-problems to be solved in parallel instead of in sequence. However, the speed-up is capped in systems that aggregate the sub-results at a single point. Researchers devised a way to remove that limit.
What’s new: A team at Carnegie Mellon University led by Xuecheng Liu and Daman Arora proposed an agentic harness called Message Passing Language Models (MPLMs). Under MPLM, an LLM distributes sub-problems among separate threads — each running its own copy of the LLM — that can communicate with one another. This approach solved two types of structured puzzles faster than alternatives.
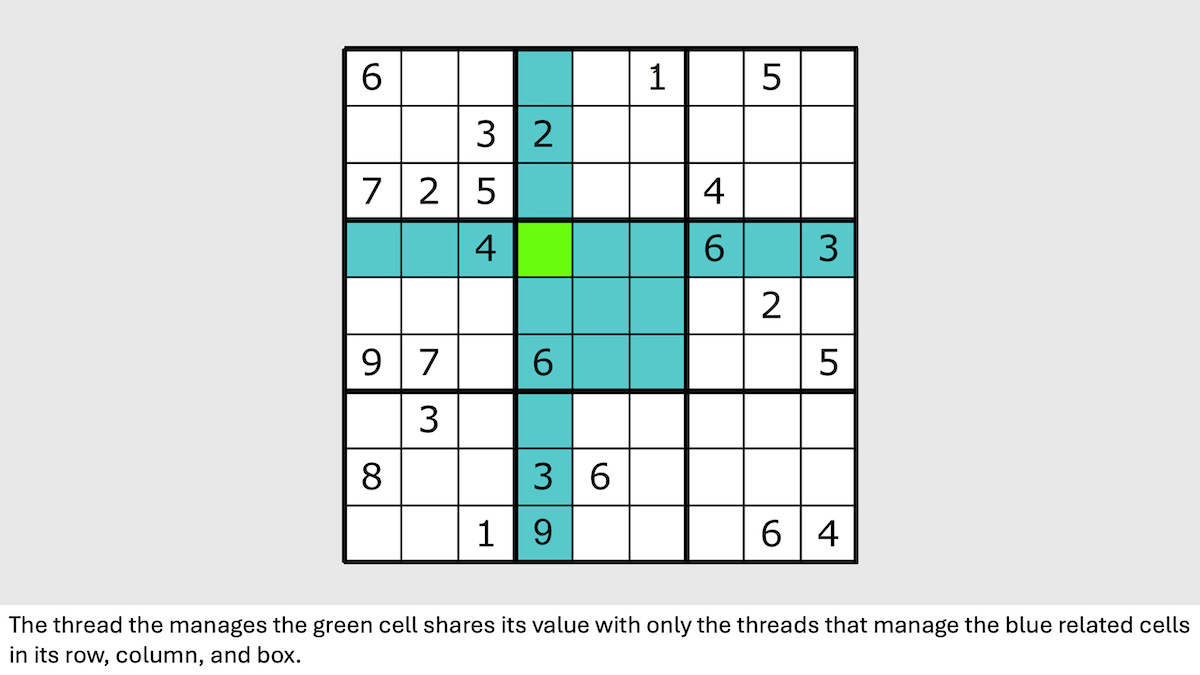
Key insight: In earlier parallelization methods, an LLM breaks down tasks into sub-tasks while a coordinator thread spawns separate threads, assigns sub-tasks to them, and collects their output. The problem with this arrangement is that the coordinator can become bogged down in reasoning, tool calls, and the like, so the subtasks must wait. But problems in which the relationships between threads are known in advance don’t require a central coordinator. Instead, related threads can communicate with one another. Enabling threads to communicate directly makes the coordinator unnecessary and limits the total load on any one thread.
How it works: Under MPLM, a model and its iterations can write commands that start threads, send results to specific threads, wait for replies, or stop threads. The authors built programs that (i) used these commands to solve puzzles and (ii) produced text traces as they considered possible solutions. They trained Qwen3-0.6B-Base on those traces. The puzzles included examples of 3-SAT (deciding whether a boolean formula can evaluate to true) and Sudoku (filling a square grid with numbers, from 1 to the number of cells in a row, column, and box, so no number repeats in any row, column, or box). The description below applies to solving Sudoku. Solving 3-SAT involved a different process.
Results: MPLM solved the puzzles faster and in fewer tokens per thread than two earlier approaches: a single thread and an agentic harness that runs parallel threads but routes their results through a coordinator.
Yes, but: MPLM's efficiency depends on knowing in advance which threads must communicate with which. It shines where that communication pattern is fixed and easy to work out, as it is in Sudoku and 3-SAT. For open-ended problems, the authors note that finding the pattern may take careful prompting or extra training. Moreover, the Sudoku examples were limited to puzzles that could be solved by elimination (known as naked singles), so the model never had to guess and check or reason more extensively across threads.
Why it matters: Models that perform tasks in a single thread can fill their context windows before they reach a solution. MPLM enables models to distribute the work among many threads that, collectively, can get the job done.
We’re thinking: The authors also prompted two larger models, Qwen3-30B-A3B and Qwen3.6-35B-A3B, to use their method to tackle problems on the LongBench-v2 long-context reasoning benchmark. Both models showed improved accuracy and faster responses (roughly a 2x reduction in average latency) in the MPLM harness. This suggests this method is generalizable to reasoning challenges beyond the relatively simple Sudoku and 3-SAT examples, although its effects do seem to be stronger on smaller models.
Work With Andrew Ng
Join the teams that are bringing AI to the world! Check out job openings at DeepLearning.AI, AI Fund, Landing AI, and LearnVector.
Subscribe and view previous issues here.
Thoughts, suggestions, feedback? Please send to thebatch@deeplearning.ai. Avoid our newsletter ending up in your spam folder by adding our email address to your contacts list.
|